








Dedicated Developer
An AI Engineer works exclusively on your project, integrated with the tools and workflows your team already uses.
Best for Ongoing model and pipeline work, eval driven iteration
Book a Consultation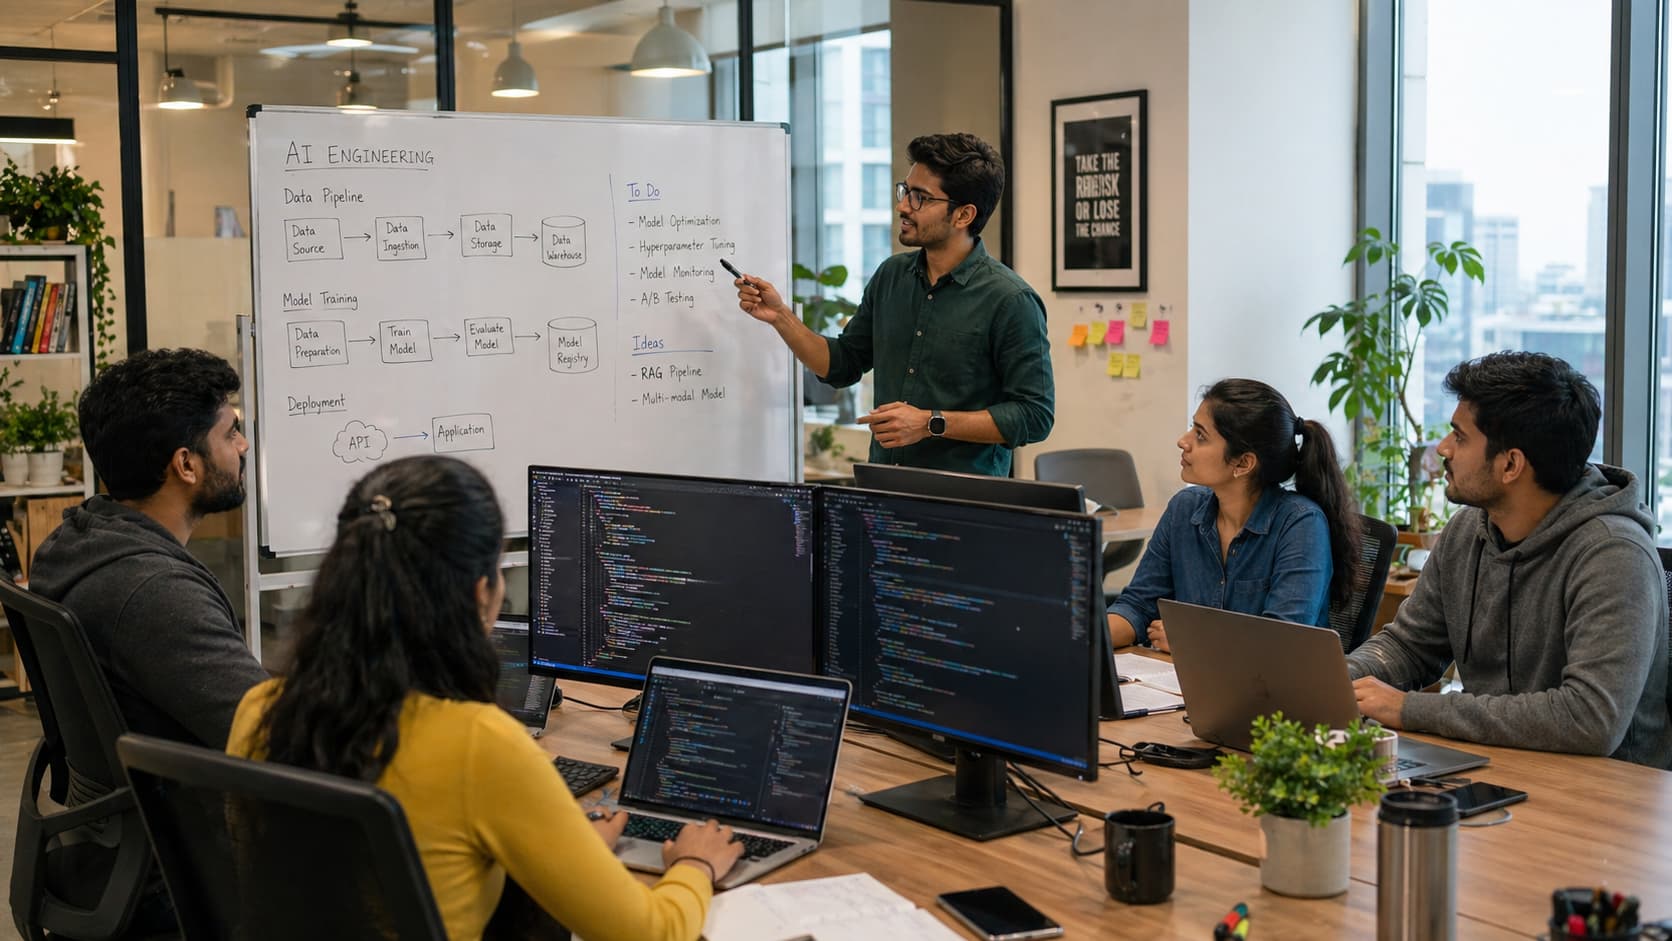
We start with frontier models (OpenAI GPT models, Claude, open source alternatives) and adapt them to your domain with retrieval, prompting or fine tuning where the use case needs it.
AI assisted evaluation checks model outputs against benchmarks built for your domain, helping the team catch accuracy regressions and hallucinations before a release.
AI assisted monitoring tracks production model performance, drift and user feedback in real time, and flags quality drops so the team can retrain the model or adjust prompts.
AI tools analyze your usage patterns to recommend the right model size, caching strategy, and batching approach, keeping inference costs predictable as you scale.
Autonomous agents that perform multi step tasks using LLMs, tool calling, and domain knowledge. Customer support, research, and workflow automation.
Retrieval augmented generation systems that ground AI responses in your proprietary data. Document Q&A, internal knowledge bases, and domain specific assistants.
Image classification, object detection, OCR, and visual inspection systems. From medical imaging to manufacturing quality control.
Named entity recognition, sentiment analysis, document classification, and text extraction pipelines for structured data from unstructured content.
Forecasting, anomaly detection, recommendation engines, and scoring models trained on your historical data for business specific predictions.
Deploy AI models into your existing applications. API wrappers, edge deployment, model serving infrastructure, and production monitoring.
VETTING PIPELINE
Our hiring process has three stages, from the application screen to a project deep dive with background verification, and every new engineer then serves a probation period.
We source engineers across India through LinkedIn, Wellfound, employee referrals and outbound headhunting. Every application is checked for stack relevance, years of experience, English and time zone overlap before it moves to a technical interview.
A live coding round of 60 to 90 minutes in the primary technology of the candidate, followed by scenario based questions on practical applications of that technology.
Candidates walk us through a recent production project, covering the architecture decisions and what they would change in hindsight. A third party background verification agency then confirms prior employment, education and identity.
New engineers then serve a probation period, and those who do not meet our bar do not continue with us.
From the first call to a developer working in your team, you choose who joins and when.
Tell us the experience level, tech stack, project scope and team setup you need. A 30 minute call is usually enough.
Vetted candidates are presented within a week, matched to the brief you shared.
Interview shortlisted developers directly, through technical interviews, pair programming or whatever your process requires.
Your developer joins your tools and standups, and onboarding completes in 7 to 14 business days.
An AI Engineer works exclusively on your project, integrated with the tools and workflows your team already uses.

We assemble and manage an AI team with a tech lead, handling delivery end to end against your requirements.

Fixed scope, timeline, and budget. We deliver the project and hand off the codebase with documentation.
Engagement terms
Read how our engagements work for the detail behind each term.
PRICING
$30 to $60 per hour
Dedicated AI engineers, by seniority
$10,000 minimum
Fixed scope projects
For comparison, the median US AI and machine learning engineer reported $189,500 in total annual compensation in the Stack Overflow Developer Survey 2025, before recruiting costs. Every engagement is scoped individually before any number becomes a quote.
Read the AI cost guideCOMPARE HIRING OPTIONS
US median from the Stack Overflow Developer Survey 2025. Freelance rate from the Upwork hiring guide for artificial intelligence engineers, read in September 2026. Unico Connect rates are our published bands.
| Hire Direct (FTE) | Freelance Platform | Unico Connect | |
|---|---|---|---|
| Cost | Median US total compensation of $189,500 a year for an AI and machine learning engineer, before recruiting costs | $35 to $60 per hour for AI engineers on Upwork | $30 to $60 per hour by seniority, $10,000 minimum for fixed scope projects |
| Who vets the engineer | Your own recruiting team | You vet each freelancer yourself | Three stage vetting, from live coding to background verification, then probation |
| Security | Your own controls | Varies by freelancer | ISO/IEC 27001:2022 certified |
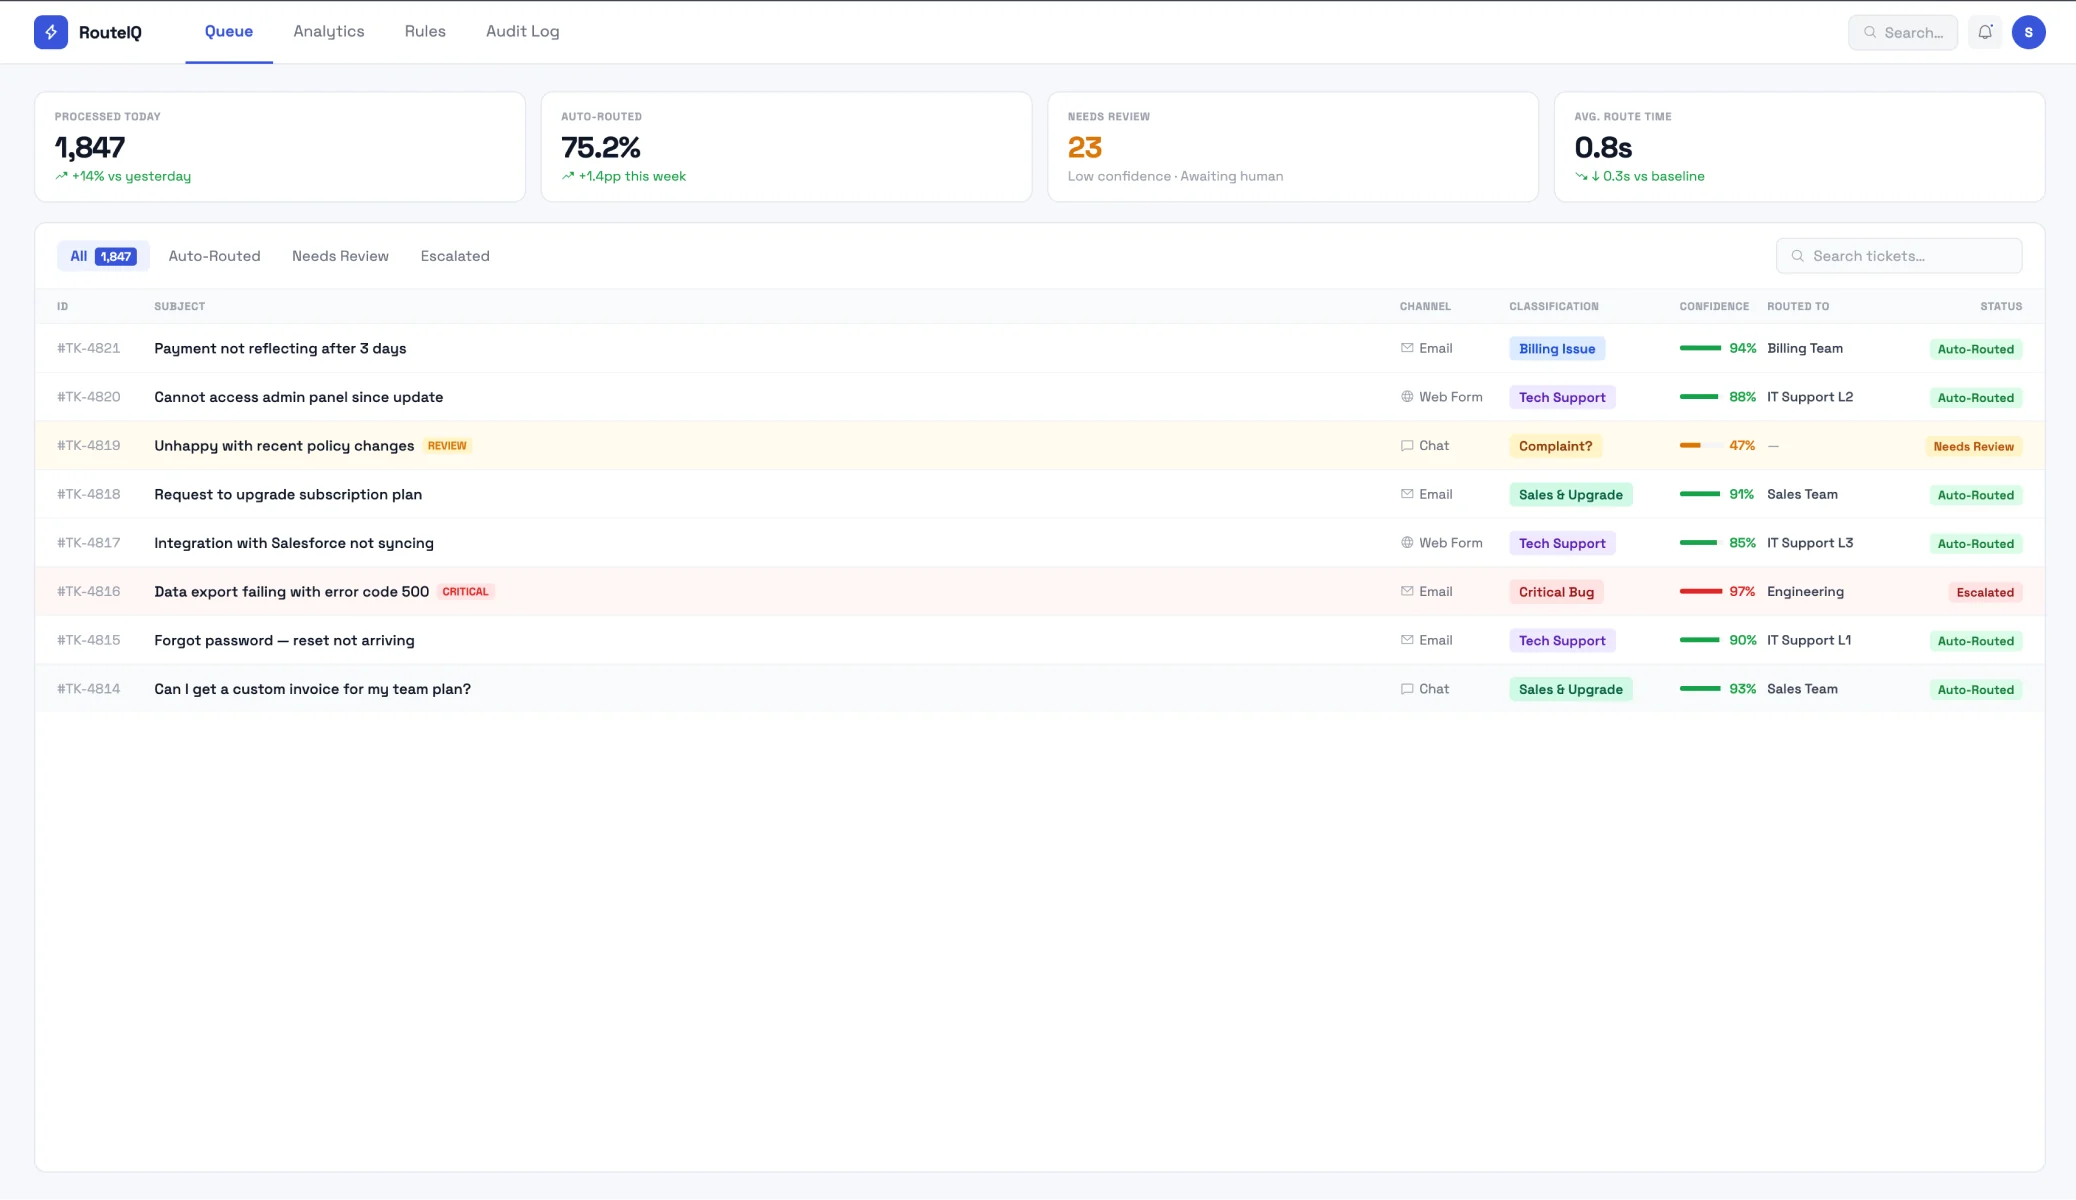
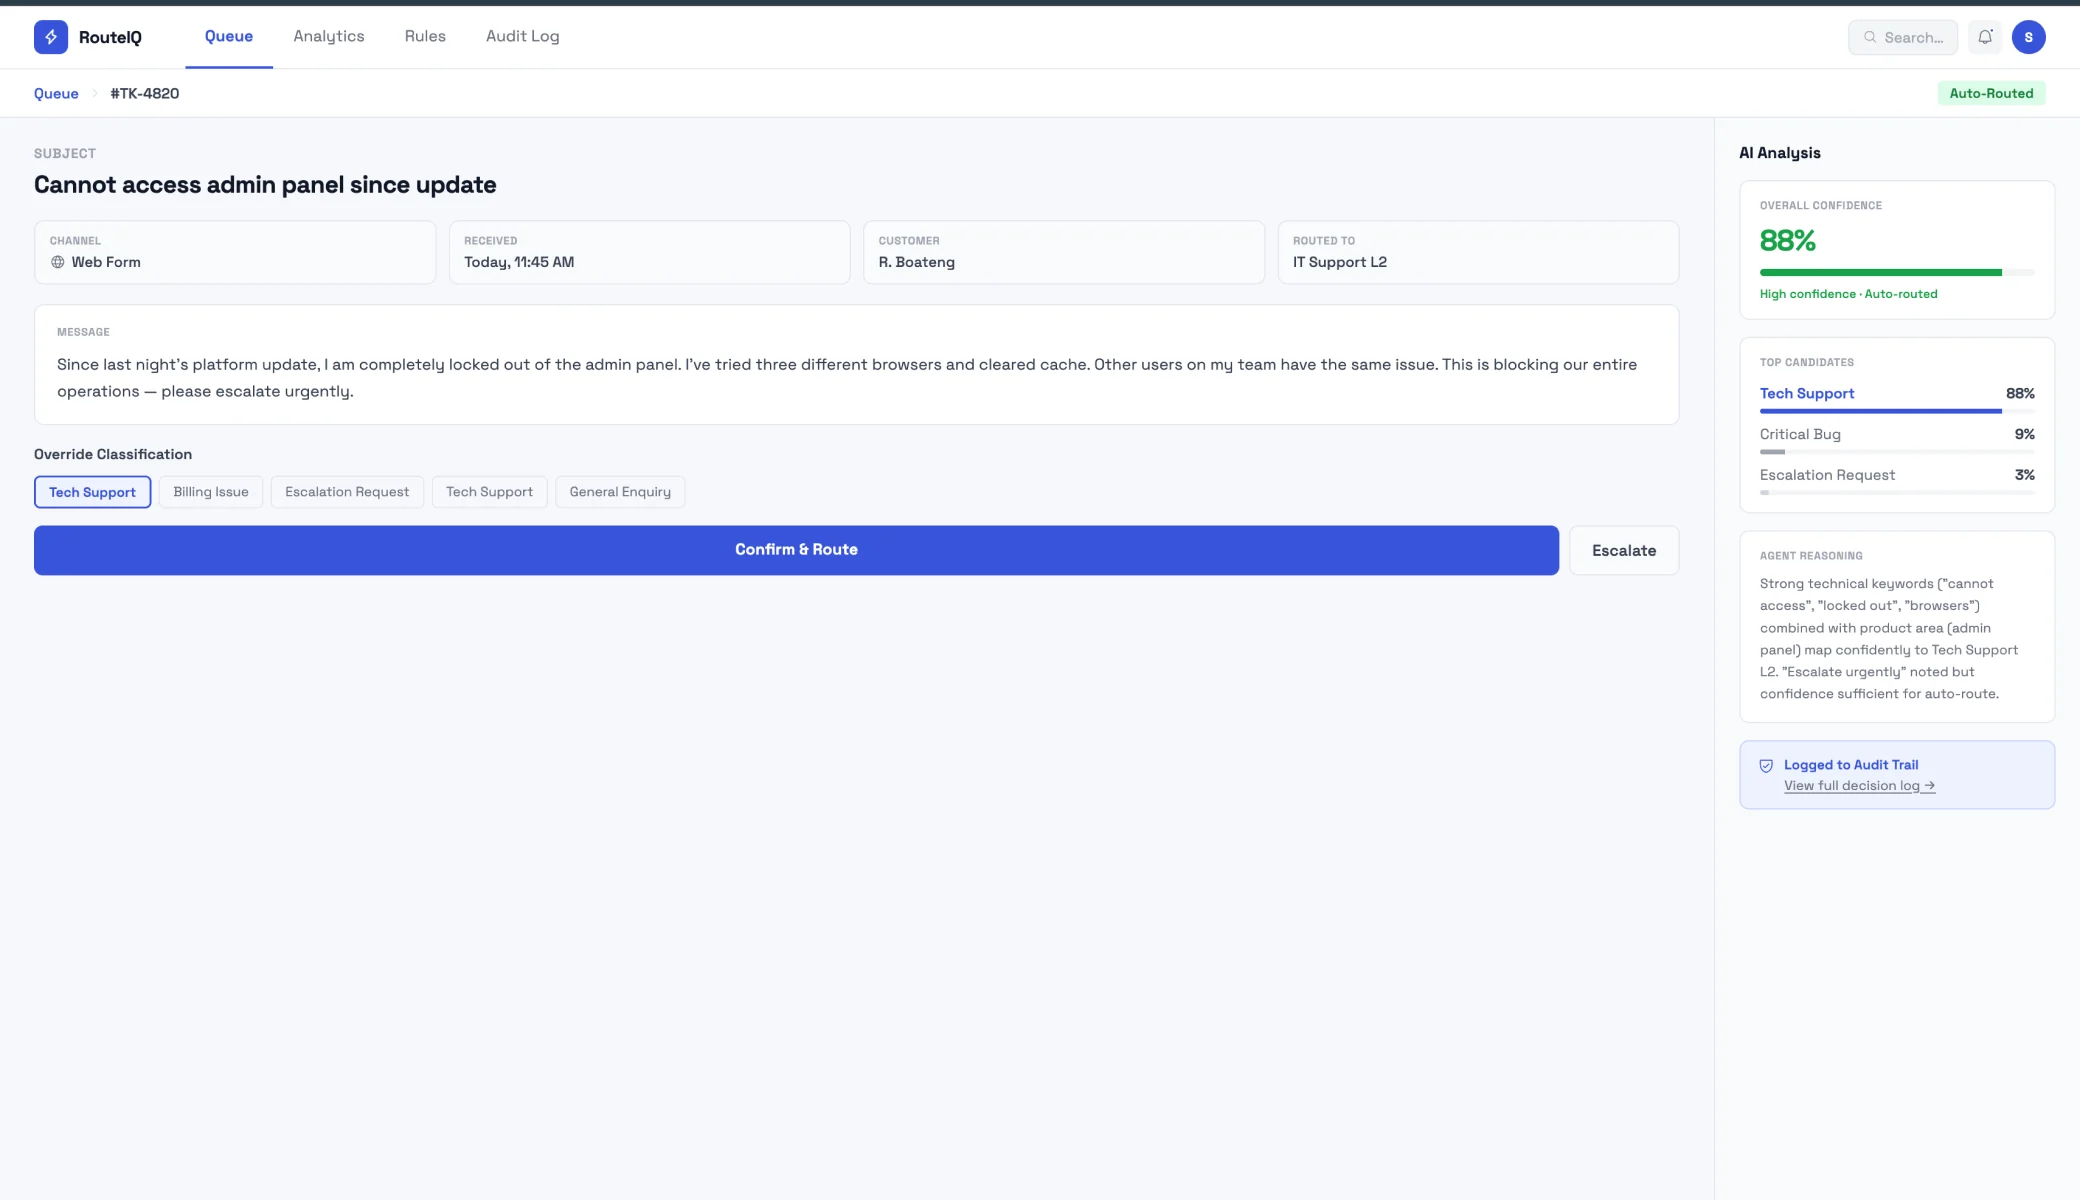
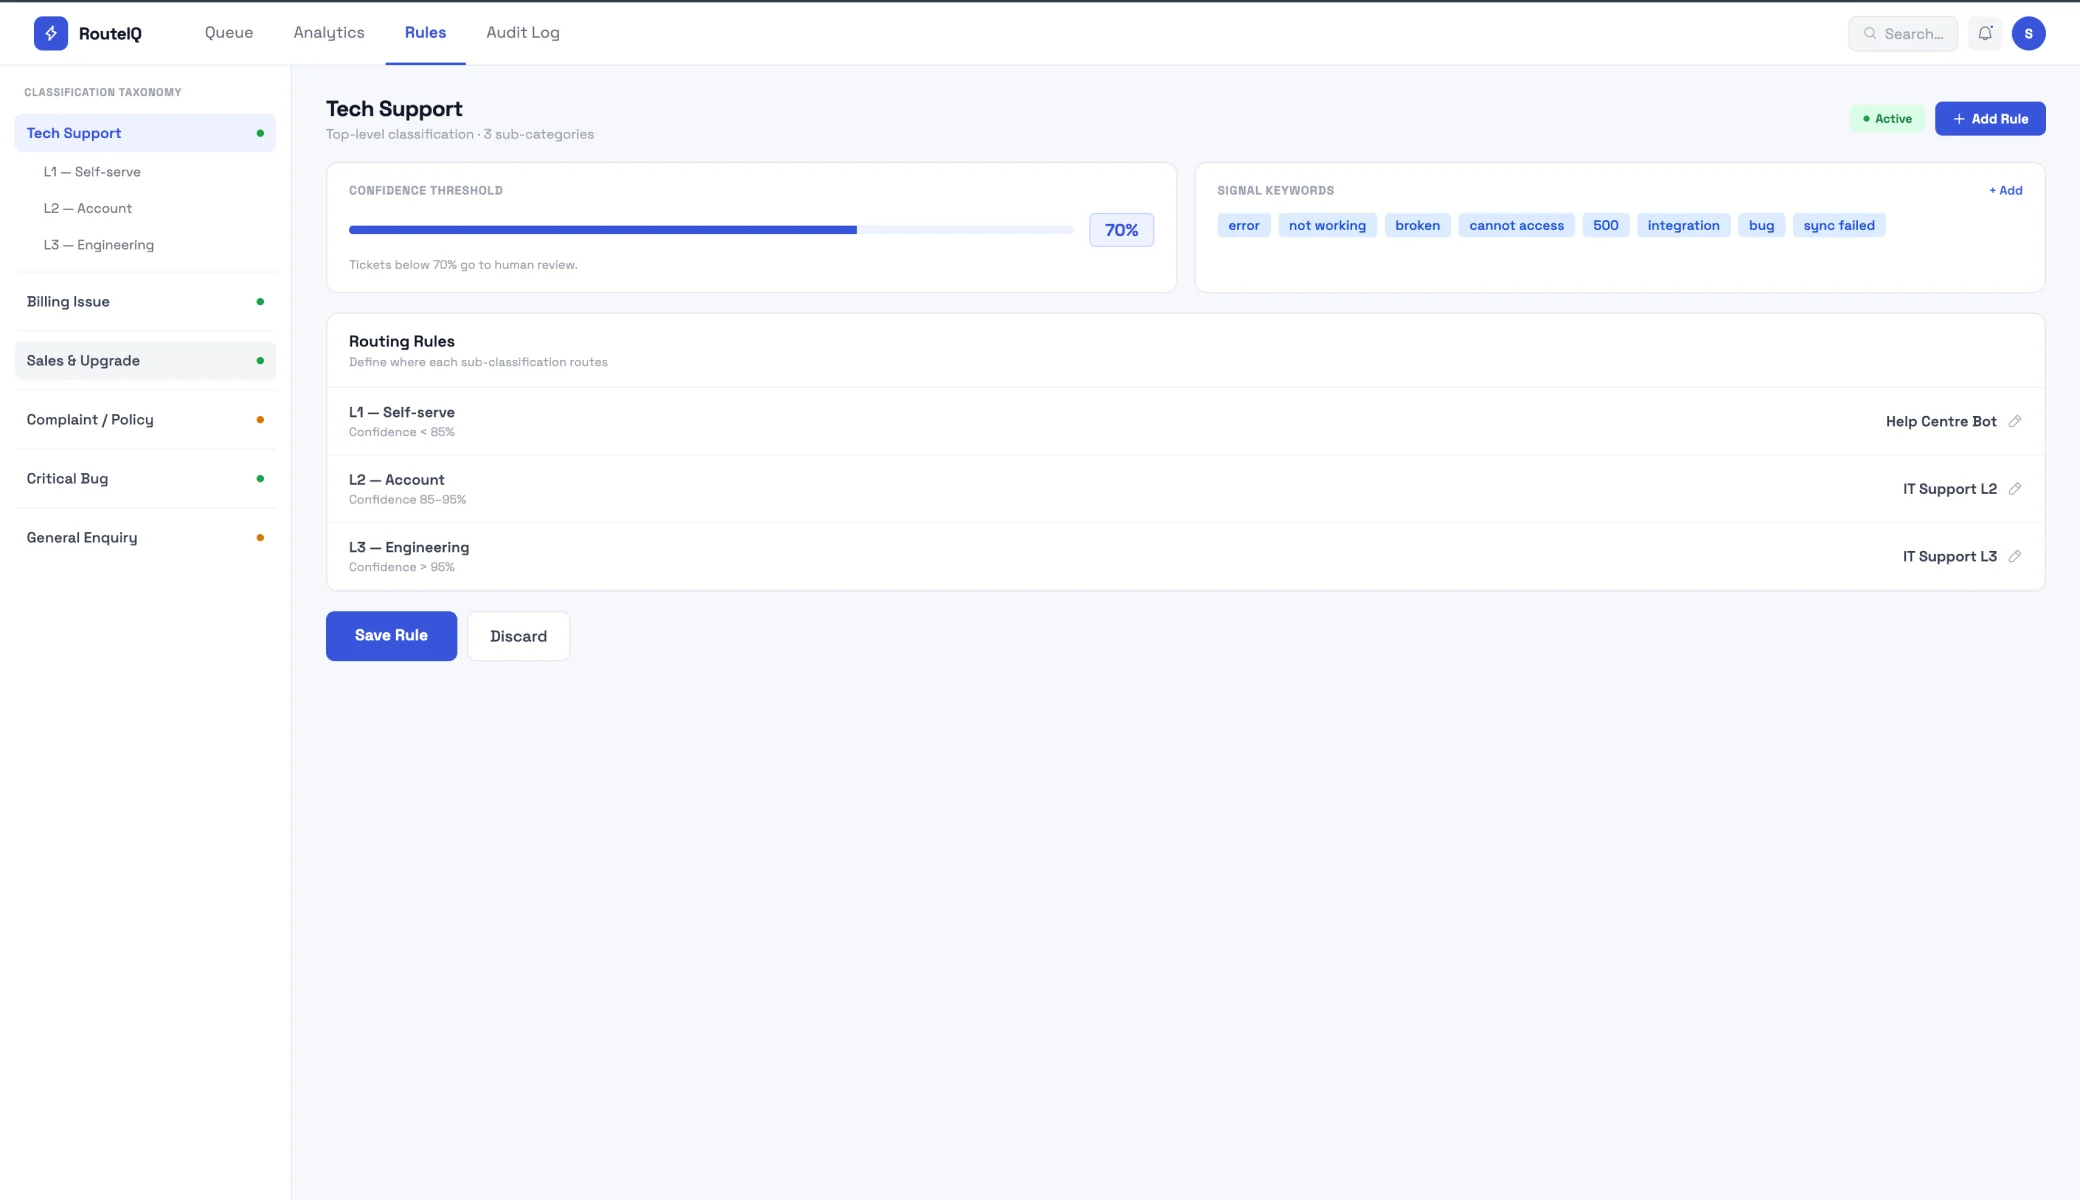
~75%
Tickets auto classified
Auto
Routing when confidence is high
Human
Escalation on edge cases
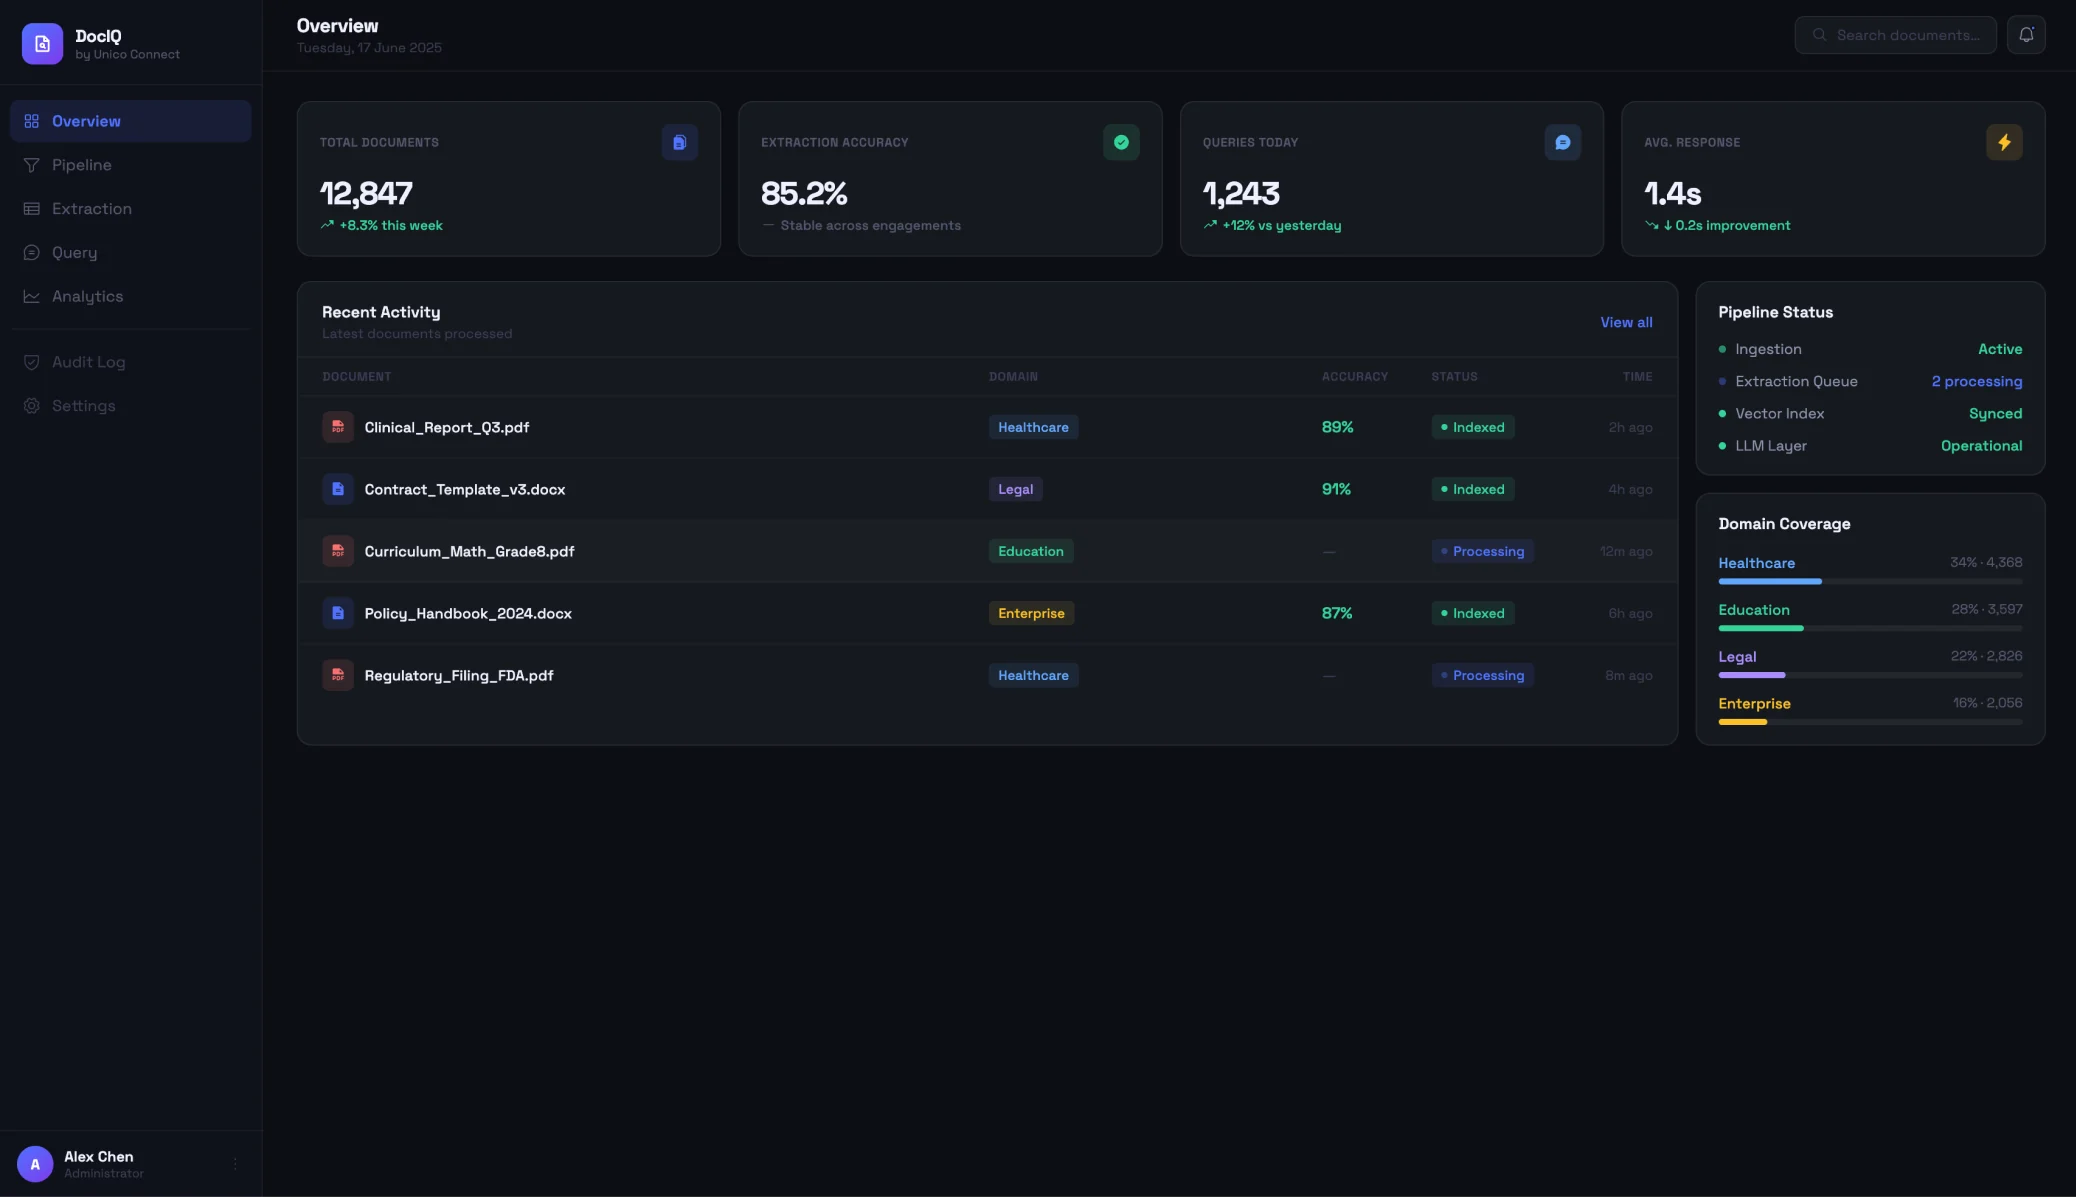
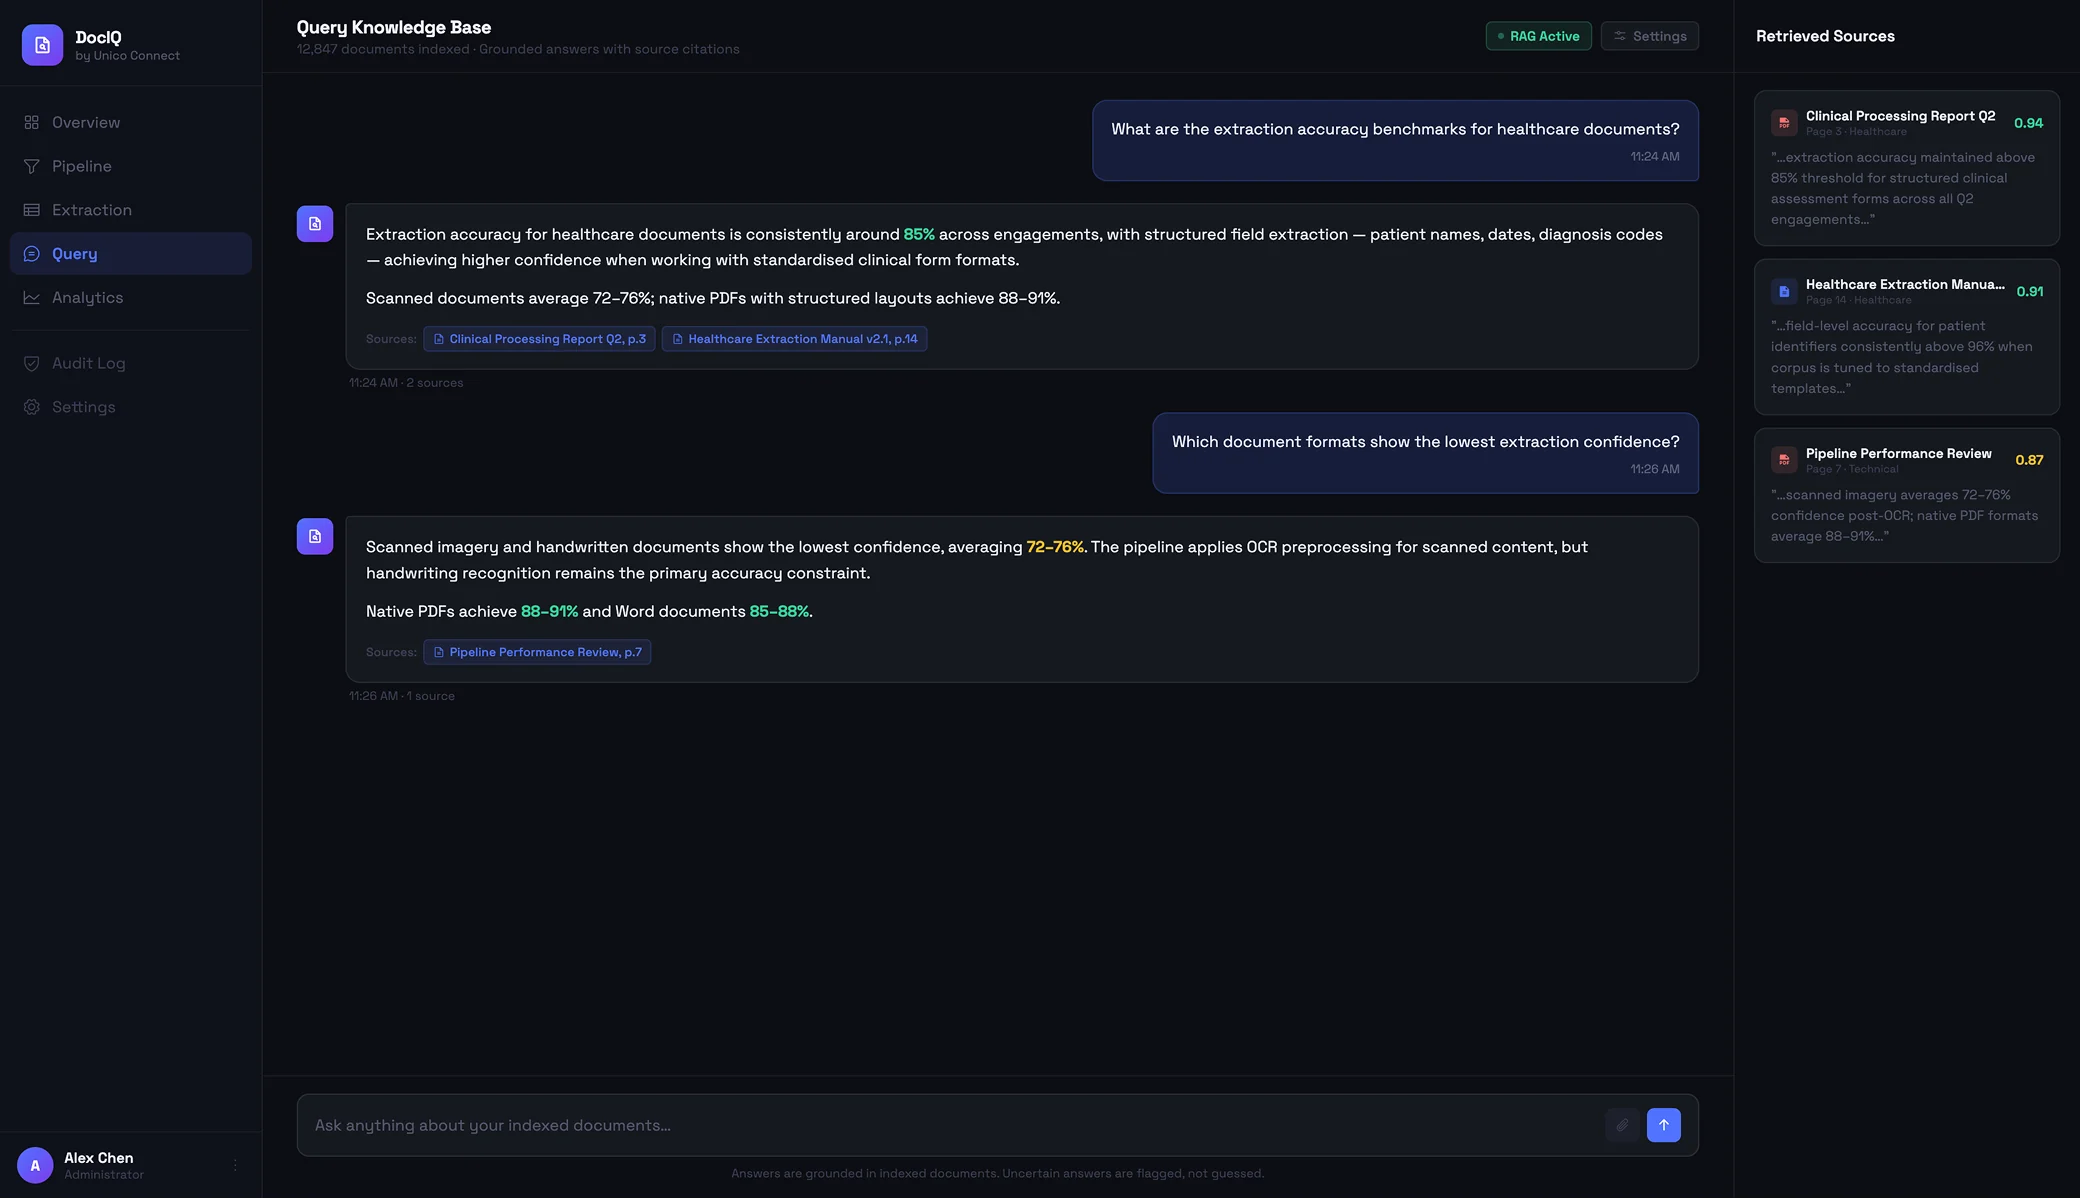
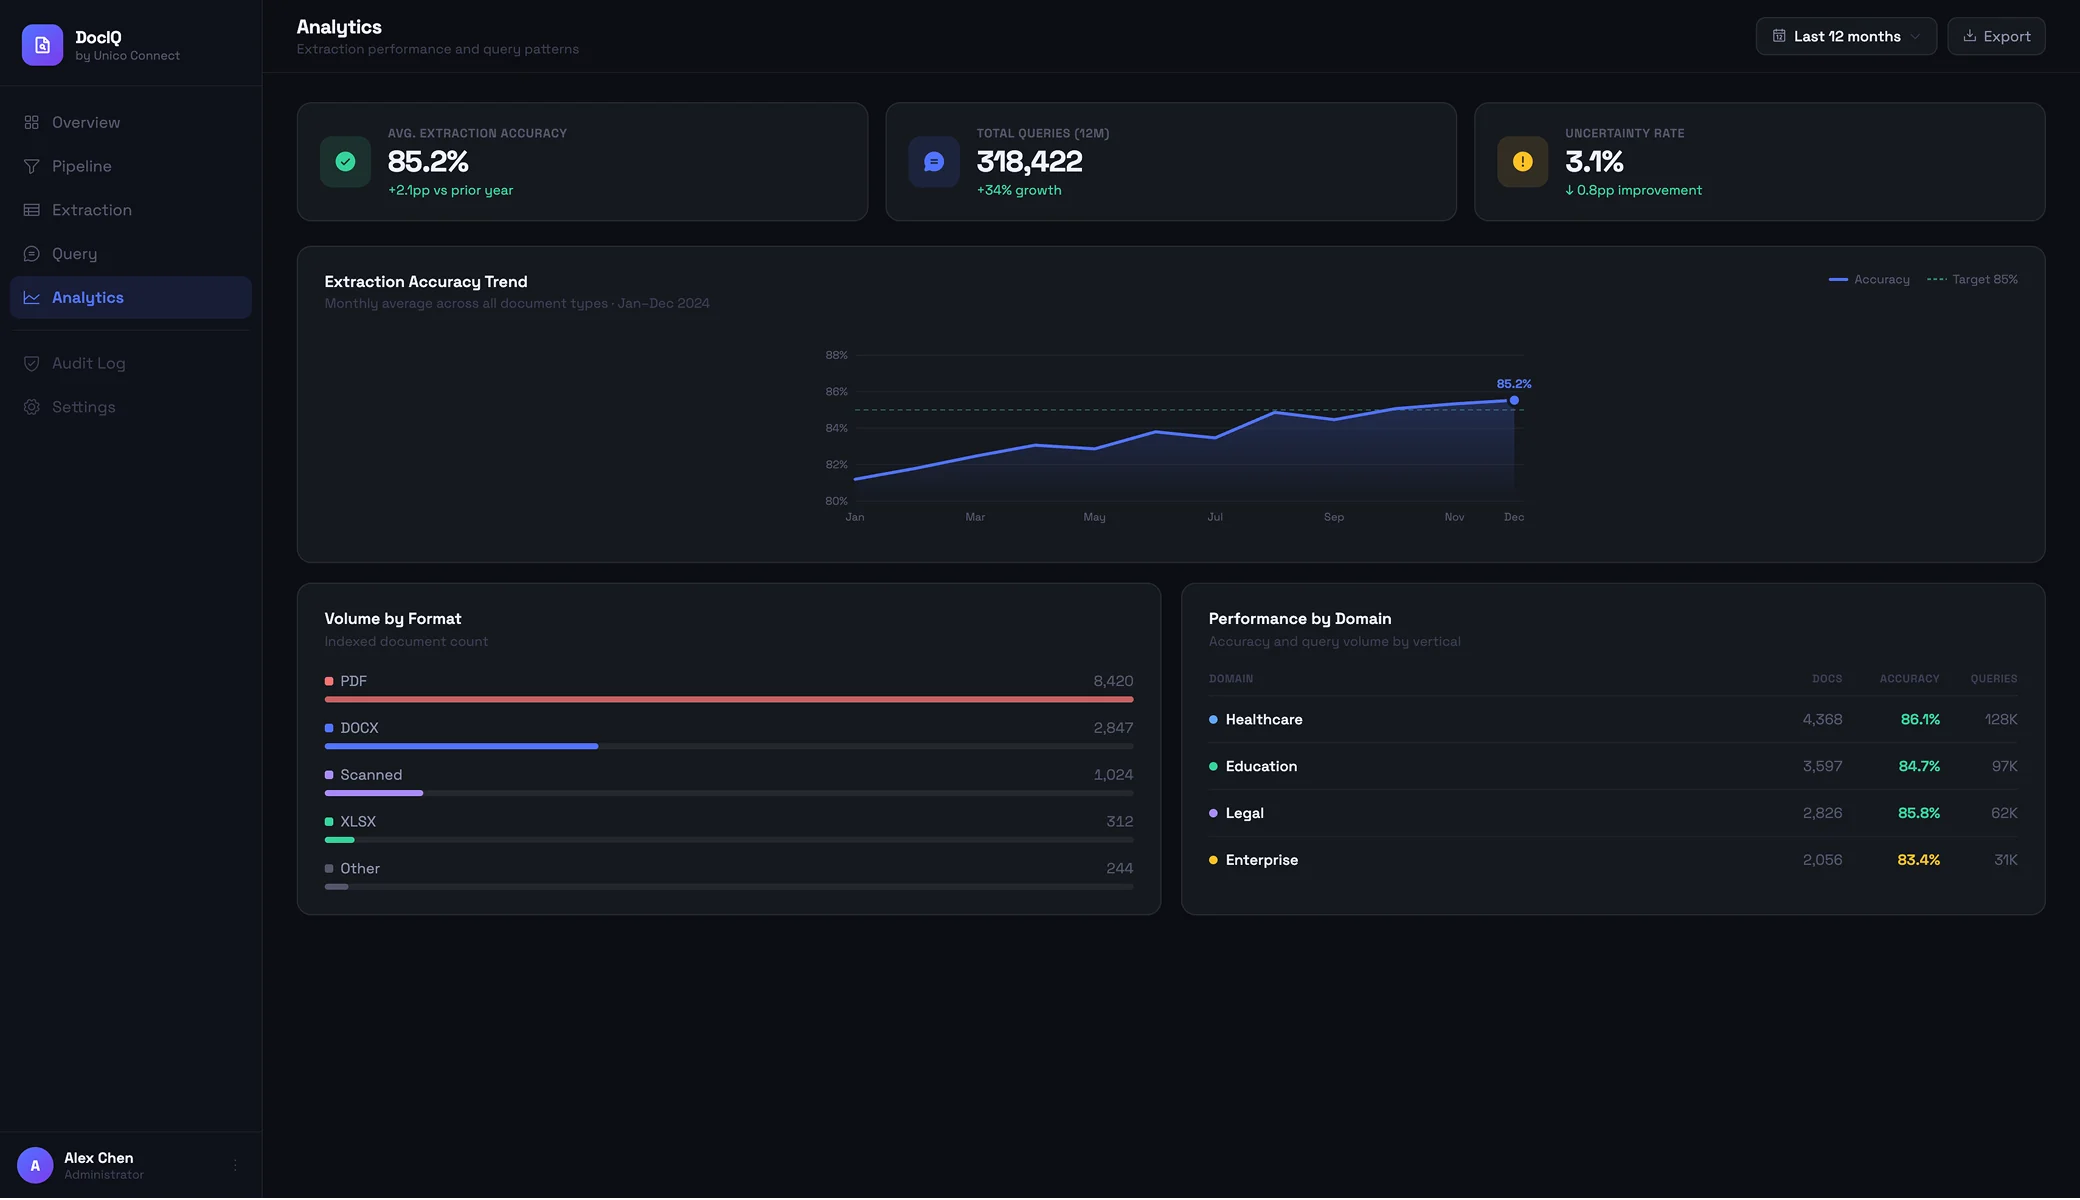
~85%
Extraction accuracy, tuned per corpus
Cited
Source referenced answers
Audit
Every field traced to its source
2
WhatsApp AI agents live
Voice
Plus text, natively
Data
Grounded in client data


Share the AI work you need on a first call, and we shortlist vetted AI engineers who match it for you to interview. Vetted candidates are presented within a week, and onboarding completes in 7 to 14 business days. To speed up the match, tell us whether the product is already in production, the problems you face and what has been tried, the work needed and any regulation or process it must follow, and the features or bugs to fix, so we can match the experience the work needs.
Beyond dedicated developers, our teams deliver complete products and platforms.
Custom AI such as computer vision, NLP, recommendation, and models tuned for production.
ExploreAutonomous agents with tool use, MCP servers, and human in the loop checkpoints.
ExplorePlug AI into existing products with semantic search, document AI, and AI powered analytics.
ExploreAutomate document processing, support triage, and workflows with agentic AI, RAG, and human in the loop.
ExploreTell us about your project. We will get back to you within one business day.
Prefer to book directly?
🗓️ Schedule on Calendly →Or email us
✉️sales@unicoconnect.com